Frankie Butler · 11 October 2026
Optimizing Site Architecture to Boost Discoverability During Rapid Feature Deployments at Scaling Tech Platforms Like Melova
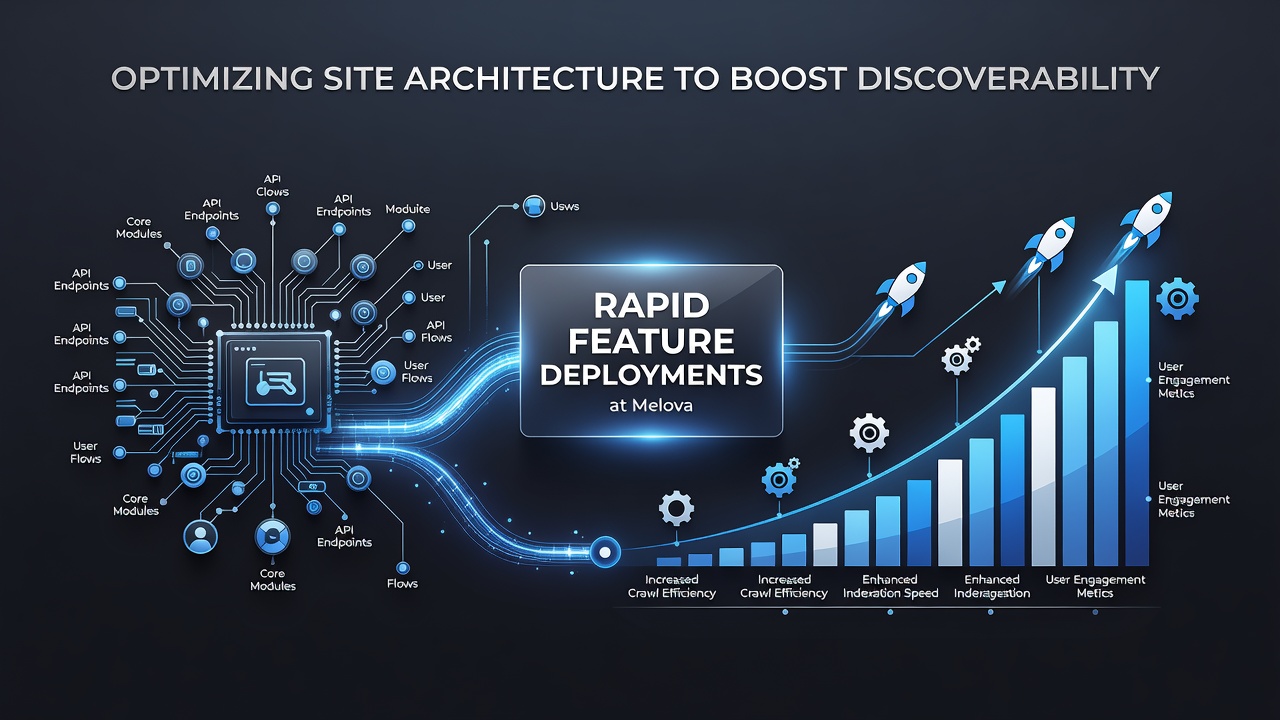
Scaling tech platforms face constant pressure to release new features while preserving search visibility and user access, and observers note that site architecture plays a central role in managing these demands. At companies like Melova, teams coordinate URL structures, internal linking patterns, and crawl directives so that updates roll out without fragmenting indexation or slowing discovery. Data from industry reports shows that platforms handling thousands of daily changes rely on modular directory hierarchies and dynamic sitemap generation to keep content reachable.
Core Elements of Resilient Site Architecture
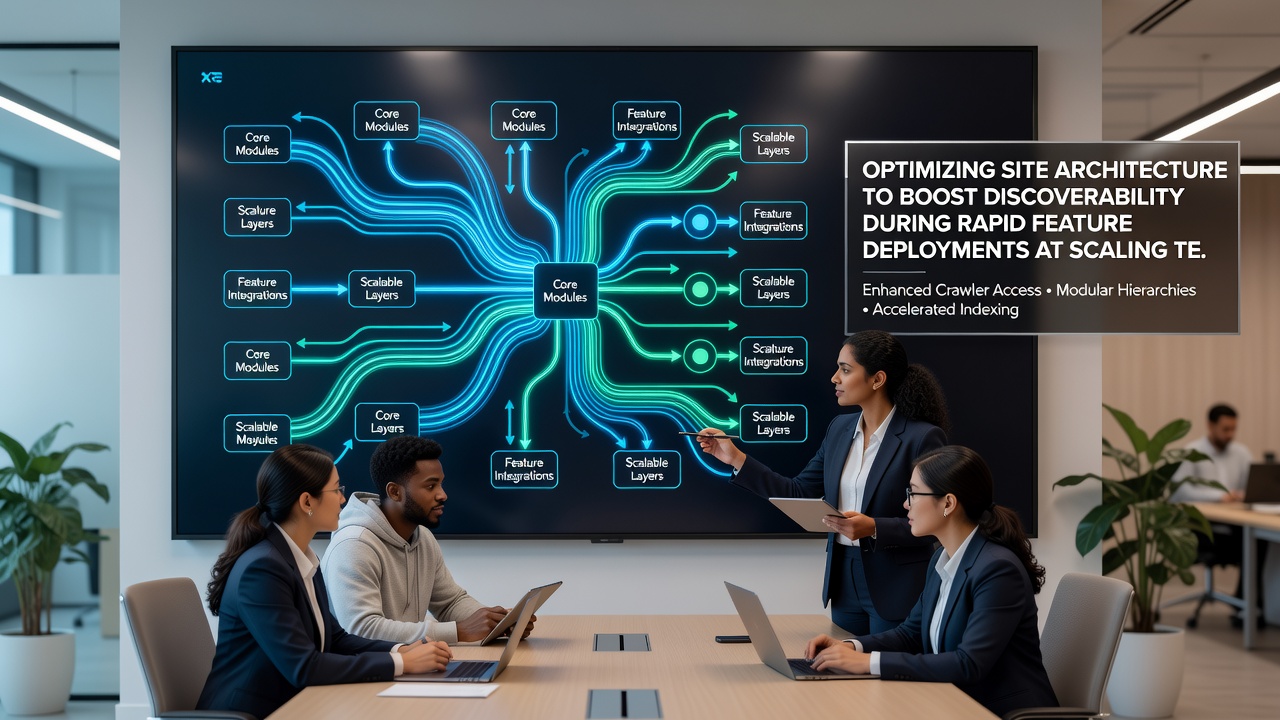
Effective architecture begins with flat directory structures that limit nesting depth, because search engines allocate crawl resources more efficiently when paths stay concise and predictable. Researchers at academic institutions have documented how excessive subfolder layers increase processing time during indexing cycles, whereas consistent naming conventions across feature branches reduce duplication risks. Platforms integrate canonical tags at the template level so that variant URLs generated during A/B testing or phased rollouts point back to primary versions without manual intervention each time.
Internal linking follows a hub-and-spoke model in which core category pages connect outward to new feature modules, and this pattern helps distribute authority while guiding crawlers through fresh content. In October 2026, several scaling platforms updated their link graphs to accommodate new API-driven sections, and logs indicated improved coverage rates within 48 hours of deployment. Structured data markup applied uniformly across content types further signals relationships between pages, allowing engines to understand context even when navigation elements shift during updates.
Managing Crawl Budget Amid Continuous Releases
Robots.txt files and meta directives receive version-controlled updates that align with deployment schedules, preventing temporary blocks on newly launched sections. According to documentation from the World Wide Web Consortium, clear directives on allowable paths maintain crawl efficiency when sites expand rapidly. W3C web architecture guidelines emphasize the value of predictable resource patterns, and platforms apply these principles by grouping static assets separately from dynamic feature endpoints.
Log analysis tools track crawl frequency per directory, revealing which areas receive disproportionate attention during high-velocity periods. Teams adjust priority values in sitemaps based on these patterns, ensuring that recently deployed modules gain timely attention without starving established sections of resources. Evidence from performance studies indicates that such targeted adjustments preserve overall indexation health even when release cadence increases.
Integration With Deployment Pipelines
Continuous integration systems trigger automated checks that validate URL generation rules and link integrity before code reaches production. These checks compare new paths against existing sitemaps and flag potential conflicts, such as duplicate slugs or broken redirects. Observers have recorded fewer indexing delays at organizations that embed these validations early in the pipeline rather than after launch.
Staging environments mirror production architecture so that crawl simulations run on realistic structures, and this practice surfaces issues like orphaned pages or excessive parameter strings before they affect live discoverability. Platforms also maintain redirect maps that evolve alongside feature additions, preserving equity from legacy URLs while new modules take their place in the hierarchy. Figures from infrastructure reports reveal that systematic redirect management correlates with steadier traffic retention during growth phases.
Monitoring and Adjustment Practices
Real-time dashboards combine search console data with server logs to surface coverage gaps shortly after deployments, and teams respond by refining internal navigation or updating schema markup. One study from a European research consortium highlighted how platforms that review these signals daily achieve faster recovery from temporary dips in indexed pages. Regular audits of JavaScript-rendered content ensure that client-side elements remain crawlable even when frameworks update mid-cycle.
Geographic distribution of servers influences latency for crawlers in different regions, and architecture teams account for this by prioritizing edge-cached resources that support consistent discovery worldwide. When new features involve user-generated sections, rate-limiting rules prevent excessive crawl requests while still allowing indexation of high-value additions.
Conclusion
Site architecture that supports rapid feature deployments centers on predictable structures, automated validation, and responsive monitoring, and platforms like Melova demonstrate these elements through coordinated updates to directories, links, and directives. Data indicates that such approaches sustain discoverability as release frequency rises, while external references such as NIST technical publications on web systems provide additional frameworks for implementation. Continued refinement of these practices aligns with evolving crawler behaviors and deployment demands observed through 2026.